The NVIDIA Vera CPU is coming soon to CoreWeave. It is the first CPU purpose-built for AI agents, running on bare metal built for AI. In the AI loop, launch day is just day one. Models and agents continuously improve through a cycle of run, observe, curate, improve, and evaluate. While GPUs generate and reason, CPUs execute everything around that work: the sandboxes, tool calls, and data pipelines every agent depends on. Each is built for its role, and they're strongest together. As post-training and agentic workloads grow, the CPU's share of every AI loop turn keeps climbing.
Specialized silicon for specialized work
AI keeps pushing infrastructure to specialize. GPUs were optimized for training, generation, and reasoning. Data Processing Units (DPUs) took over networking, storage, and infrastructure tasks. Agentic AI demands the next optimization: silicon built for executing agent work at fleet scale, with performance that holds under load. That work needs dedicated CPU capacity that scales with the workload, in concert with the GPU fleet, on one platform.
NVIDIA Vera is the first Arm-based CPU built for AI agents, with 88 custom Olympus cores designed for the branch-heavy, memory-bound work agents generate. Reinforcement learning environments, post-training pipelines, and data pre-processing now run at fleet scale. Sandboxed agent execution runs across all of it, in training and at inference time, and every tool call and code run lands on a CPU core. In CoreWeave’s testing we achieved more than 3x faster agent sandbox startup times on NVIDIA Vera CPU compared to an alternative x86 CPU.
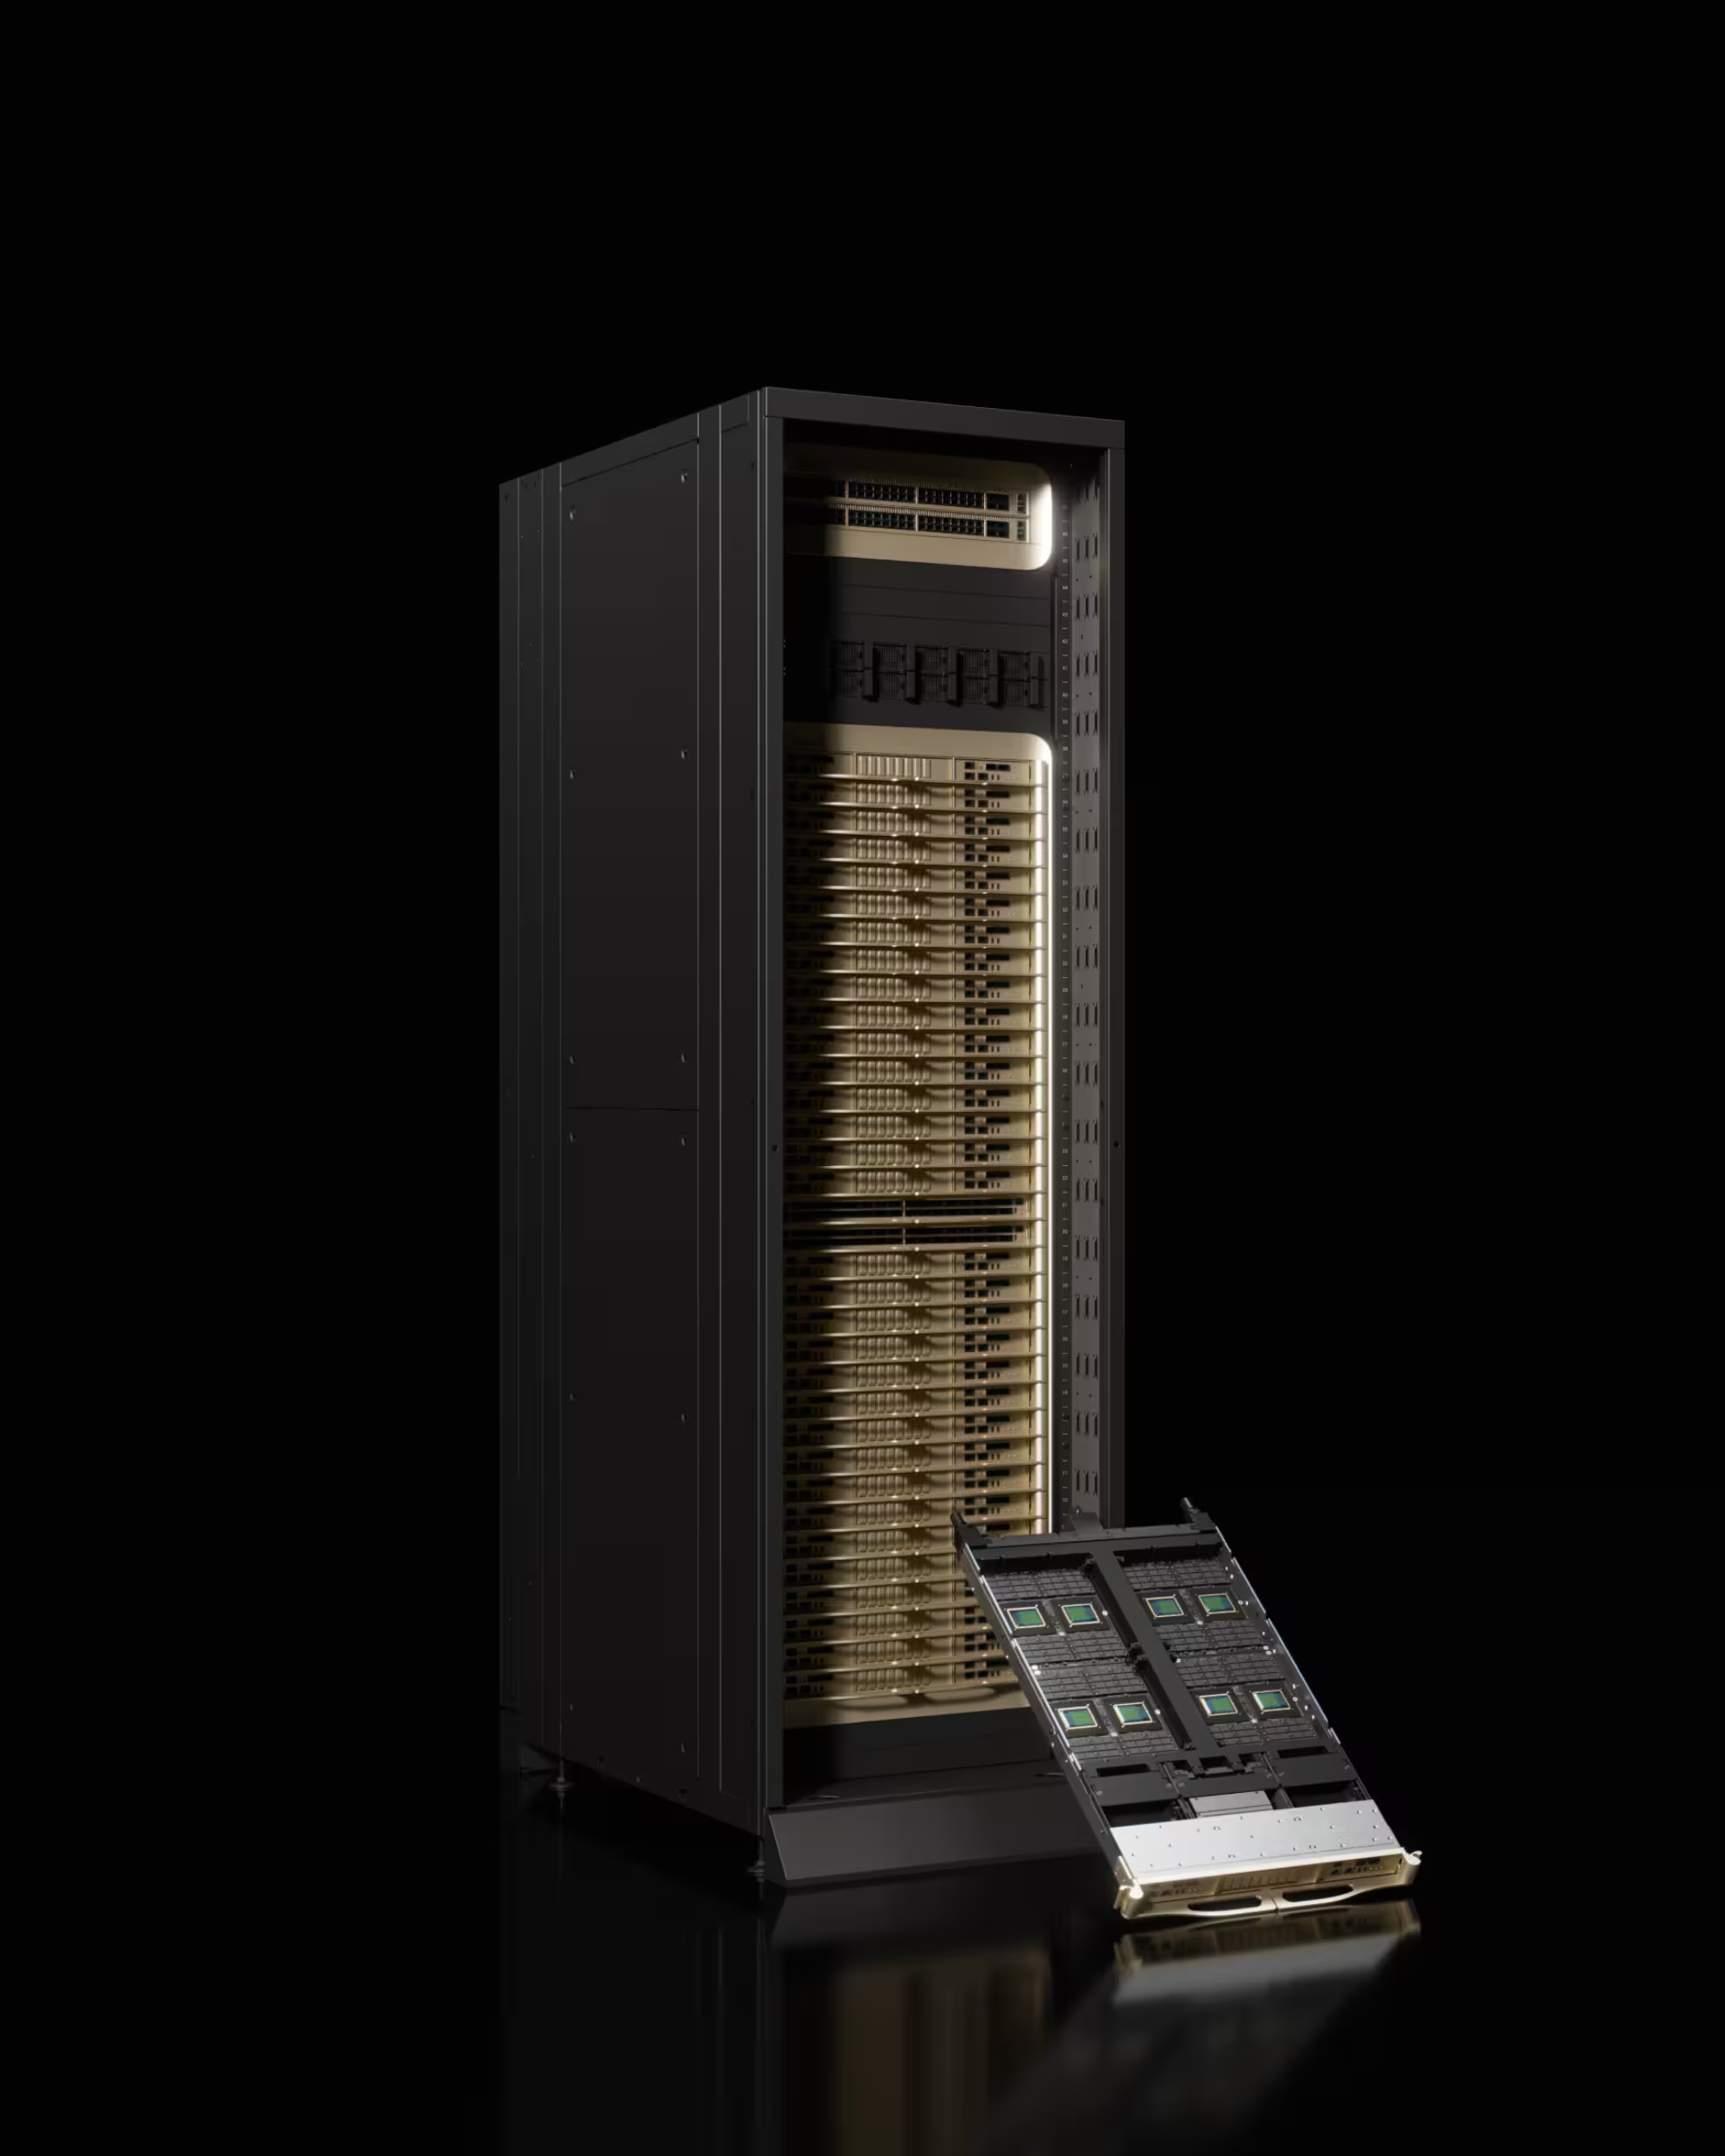
Every Vera Rubin NVL72 compute tray pairs two Vera CPUs with four Rubin GPUs, for 36 CPUs and 72 GPUs per rack, working side by side. Standalone Vera capacity takes that same specialization and scales it independently, sized to your loop. On CoreWeave, Vera runs the way the rest of your fleet does: bare metal, under the same platform, consumption models, and economics.
11,000 concurrent environments in a single rack
The unit that matters in agentic AI is how to scale the number of concurrent environments. The ceiling is how many agents a node can hold before per-environment performance turns slow and unpredictable. Vera raises that ceiling in silicon: Spatial Multithreading gives each thread its own dedicated share of the processor instead of making threads compete, keeping performance predictable under full load. CoreWeave raises it further in infrastructure: bare metal with no hypervisor overhead, plus a DPU on every Vera node offloading networking, storage, and operational tasks so your workloads keep every core.
Each NVIDIA Vera CPU node has:
- 2x NVIDIA Vera CPUs with 88 cores each
- 1.5 TB RAM
- 15.36 TB NVMe local storage
- BlueField-4 DPU, 800Gbps
The result at rack scale on CoreWeave:
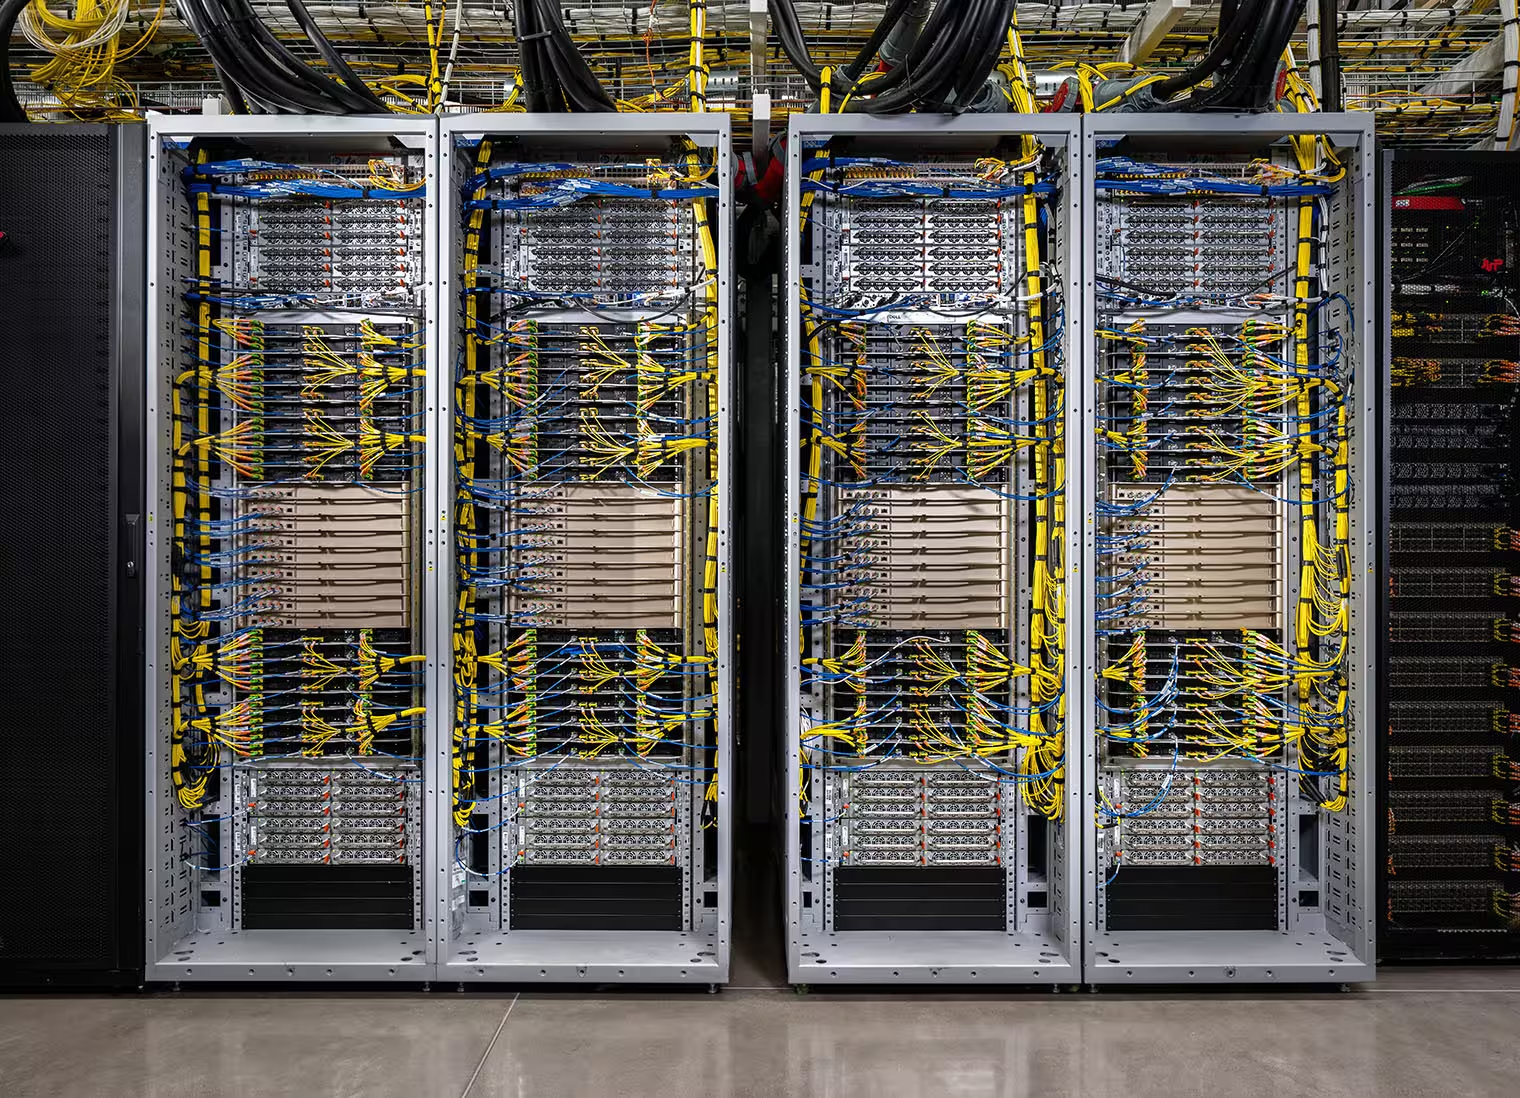
- 128 Vera CPUs and 11,264 cores packed into a single rack
- 11,000+ concurrent environments per rack
For teams planning in hundreds of thousands of environments, the rack becomes the planning unit, not the node.
Match CPU capacity to workload shape
Demand for data preprocessing pipelines and RL training episodes is bursty and hard to predict. A single step in the AI loop might need tens of thousands of environments for an hour, then virtually nothing until the next run. Buy for the peak and capacity sits idle. Buy for the average and training waits.
Because Vera delivers predictable performance at scale, CoreWeave’s consumption models let you buy the shape of your workload rather than idle CPU cycles:
- Committed capacity carries your steady base.
- Serverless spillover catches the spikes.
- Spot capacity runs interruptible work at up to 60 percent savings, with a 7-minute preemption warning so jobs checkpoint and drain cleanly.
And the burst never leaves your platform. CoreWeave Sandboxes on CoreWeave Kubernetes Service (CKS) and Serverless run isolated environments for RL, agent tool use, and evaluation natively alongside your training clusters on capacity you already hold. A committed CPU that would otherwise sit idle between runs goes to agent and evaluation work at no charge beyond the compute itself. Because it’s all on the same purpose-built AI infrastructure, you scale instantly without moving data between providers. One control plane spans the GPU and CPU fleet: CKS, CoreWeave SUNK, and CoreWeave Mission Control.
Right silicon, right workload
Agent execution, RL environments, and data pipelines each run best on different silicon, and the right answer shifts as your loop evolves. With Vera, NVIDIA joins AMD EPYC and Intel Xeon in CoreWeave's multi-vendor CPU portfolio, all bare metal, all under one operating model. Match every workload to the silicon it runs best on, and change the answer without replatforming.
Vera also brings Arm capacity that matches your GPU estate. Vera CPU instances are architecturally consistent with the Arm hosts inside modern NVIDIA GPU systems, including the Vera CPUs inside Vera Rubin NVL72, so one toolchain runs across the fleet.
Run the AI loop on the right silicon
The Vera CPU is coming soon. If your sandbox fleets, RL environments, or data pipelines are outgrowing general-purpose CPU capacity, contact us, and we'll plan capacity with you.