Improve
Fine-tune a model on curated examples, evaluate how its behavior changes, and carry the resulting checkpoint into inference or further training with Serverless RL.

Fine-tune LLMs on examples of the behavior you want while CoreWeave manages elastic GPU capacity and distributed training. Move between supervised fine-tuning (SFT) and reinforcement learning (RL) in one workflow without shuttling artifacts across systems.
CoreWeave Forge connects the data, training, evaluation, and inference behind your AI application. Serverless SFT turns examples of the behavior you want into a task-specific model that you can test, evaluate, and continue improving.

Fine-tune a model on curated examples, evaluate how its behavior changes, and carry the resulting checkpoint into inference or further training with Serverless RL.

Serverless SFT is a managed supervised fine-tuning capability in CoreWeave Training. It trains a model on curated input-and-output examples while CoreWeave manages the GPU infrastructure and distributed training backend.
Use Serverless SFT when examples can demonstrate the behavior the model should learn. Common uses include teaching a task, output format, response style, or domain pattern; distilling behavior into a smaller model; and preparing a model for reinforcement learning.
Serverless SFT uses labeled conversations that show the desired response. Training data can include system, user, assistant, and tool messages, including examples of tool calls when those are part of the task.
No. You configure and run the training loop through ART while CoreWeave provisions and manages the underlying GPU infrastructure.
Serverless SFT trains low-rank adapters (LoRAs) that specialize a base model for your task. The resulting adapters are stored and versioned as artifacts in your Weights & Biases account.
Yes. Serverless SFT and Serverless RL both use ART. You can start with supervised examples and continue from the updated model with reinforcement learning when the application can score outcomes.
Trained LoRA adapters are stored as versioned Weights & Biases Artifacts. You can also save them locally or to third-party storage for backup.
Models trained through Serverless SFT are automatically available through Serverless Inference. Use the model endpoint to test a checkpoint or connect it to your application and evaluation workflows.
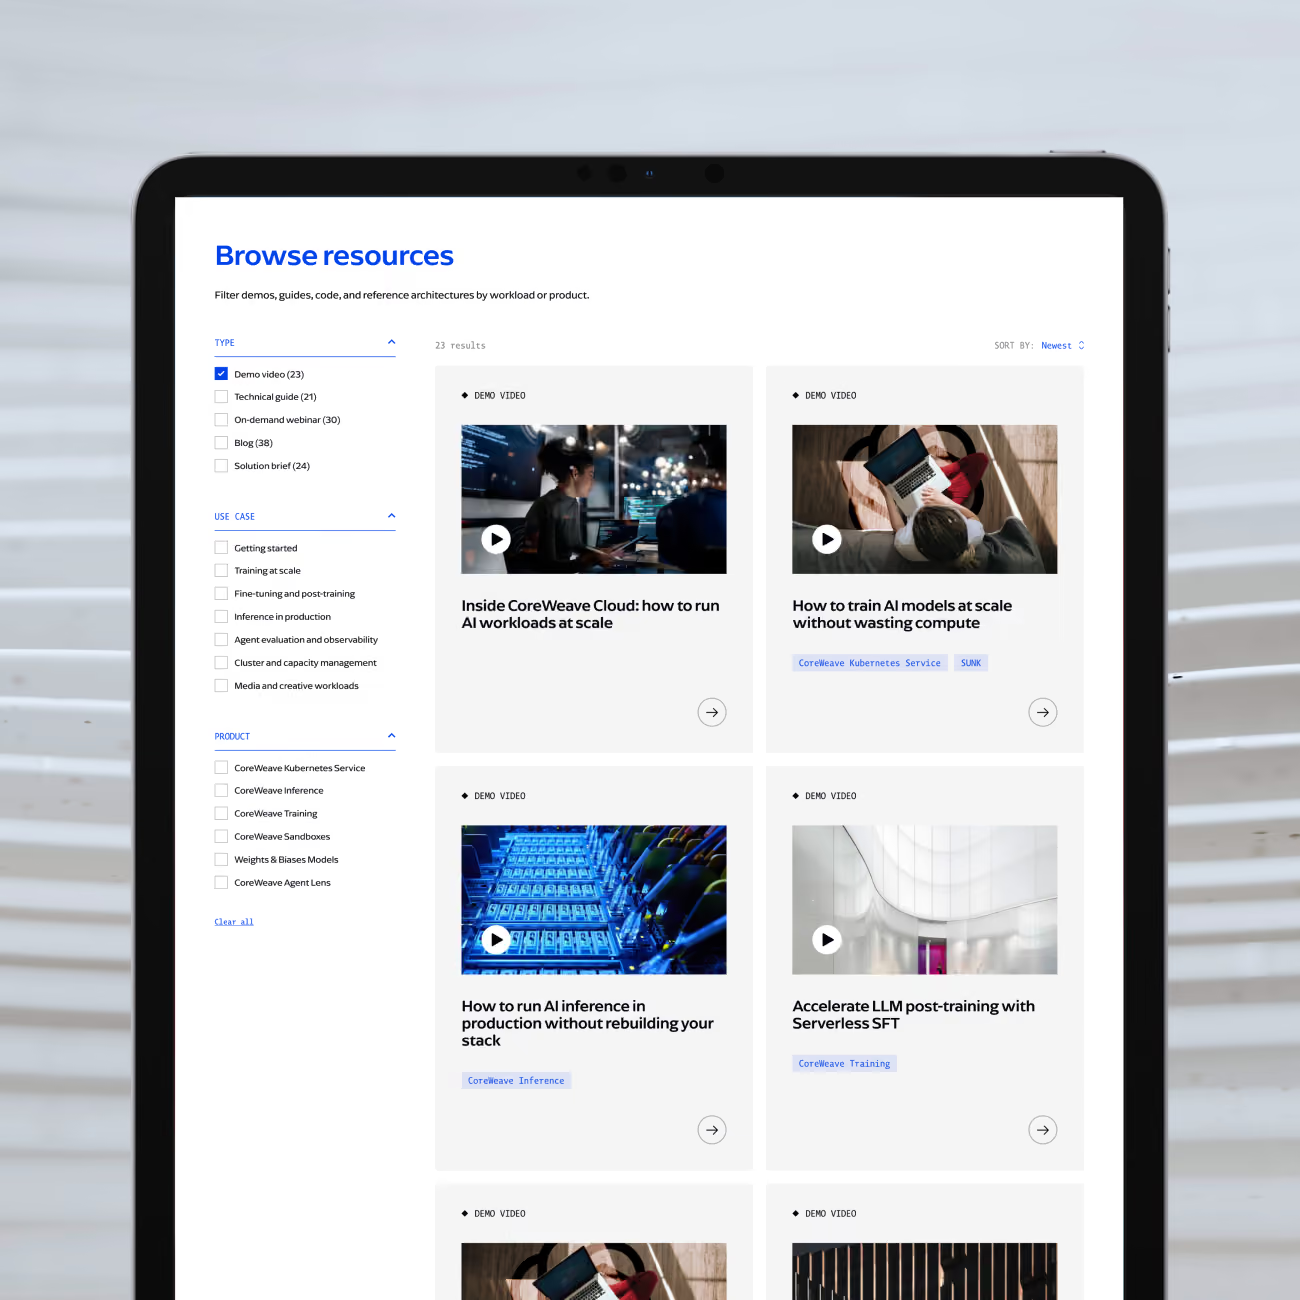
Explore demos, code, and technical resources for every stage of the AI loop. Learn how researchers, developers, and CoreWeave engineers build, observe, evaluate, and improve AI systems—and put those insights to work.
Bring your curated examples. CoreWeave runs the GPUs and distributed training while you keep control of the training loop. Test the checkpoint with Serverless Inference, then continue with Serverless RL when you're ready to optimize for outcomes.