The arrival of the NVIDIA Vera Rubin architecture raises the bar for compute performance and energy efficiency, with the architectural flexibility next-generation workloads demand.
For agentic AI, large-scale analytics, and HPC, memory capacity and bandwidth are often the limiting factors. NVIDIA HGX Rubin NVL8 brings HBM4 and sixth-generation NVIDIA NVLink together in an eight-GPU node built for those workloads, and it's coming this quarter to CoreWeave Cloud. Here's what it delivers, where it fits, and how we're preparing to run it.
NVIDIA HGX Rubin NVL8 delivers performance gains at lower operating costs
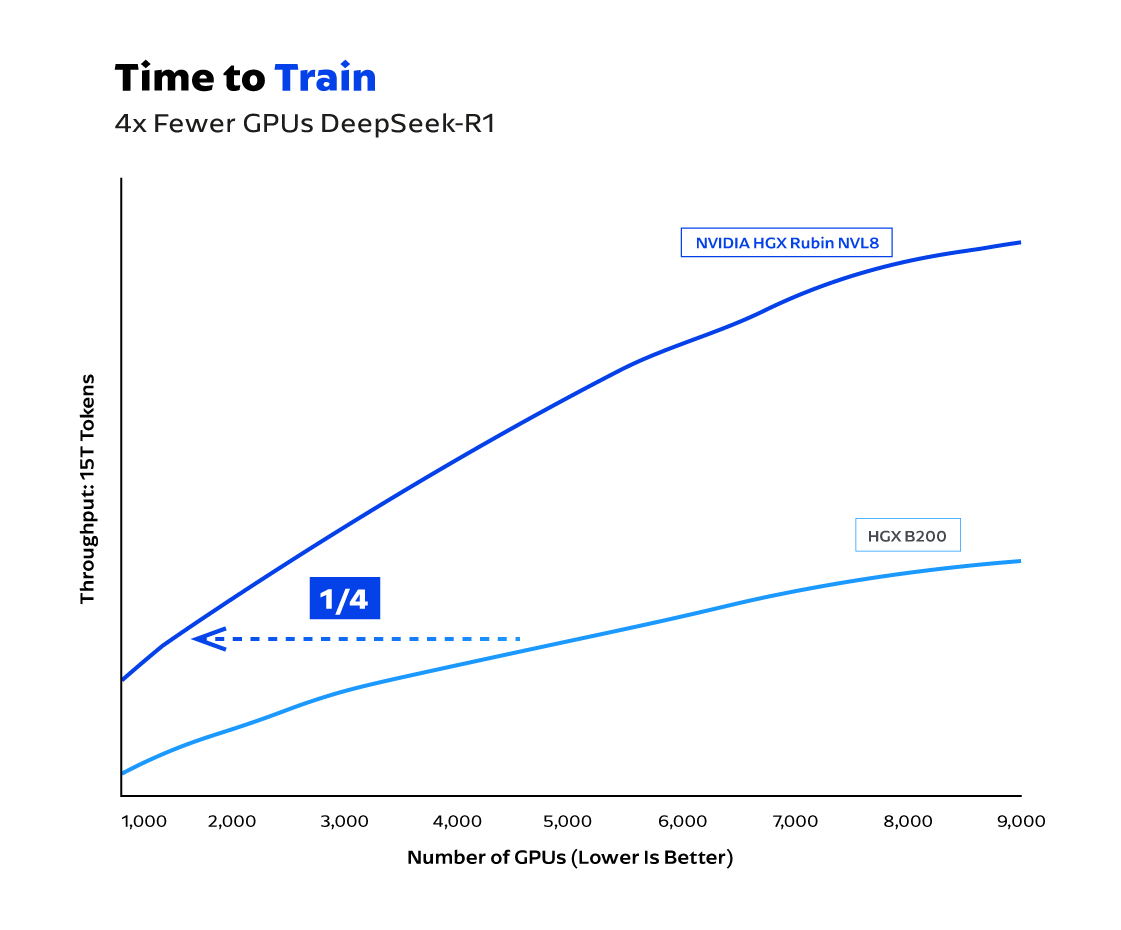
HGX Rubin NVL8 integrates eight NVIDIA Rubin SXM GPUs onto a single baseboard. NVIDIA indicates the system delivers up to 10x higher token throughput than previous architectures while matching training performance using 4x fewer GPUs. For engineering teams, this efficiency translates directly into lower operating costs, faster iteration cycles, and the ability to serve real-time, multi-step reasoning workloads at scale.
The key hardware specifications enabling these performance gains include:
- Increased memory: 2 TB of total HBM4 and 130 TB/s of aggregate memory bandwidth, enabling real-time processing of massive datasets in memory for accelerated data analytics and high-throughput agentic workflows.
- Low-latency GPU interconnect: Sixth-generation NVLink at 24 TB/s of within-node NVLink Switch bandwidth, driving ultra-low latency inter-GPU communication for complex tensor-parallel agent inference and tight HPC simulation loops.
- High-bandwidth scale-out networking: Eight NVIDIA ConnectX-9 SuperNICs provide up to 800 Gb/s of backend connectivity per GPU, supporting communication across nodes for distributed training, HPC, and large-scale data analytics workloads.
- Infrastructure offload: NVIDIA BlueField-4 provides frontend connectivity and supports networking, storage, and security offloads, helping preserve host CPU resources for application workloads.
For agentic AI, a 10x higher token throughput means more agents and users can be served on the same infrastructure, so every developer gets fast, multi-step help even during peak hours. With this ultra low latency and high-bandwidth networking, HPC simulations spend less time waiting on GPUs to share data, so a drug discovery team can screen more candidate compounds per day and get results to researchers sooner. And data analytics workloads can move large datasets between nodes faster, so a financial services firm can rerun risk analytics on the day’s transactions and give analysts updated views before markets open.

Unlocking peak performance with the CoreWeave advantage
CoreWeave completed the industry's first bring-up, validation, and benchmarking of NVIDIA Vera Rubin NVL72, and customers are already seeing results. On Vera Rubin NVL72, Cognition achieved 4.8x higher SWE-2 inference throughput and 3.8x faster output token speed for RL.
Building on this momentum, CoreWeave offers a specialized platform with features and tools designed to maximize efficiency and scale the performance of HGX Rubin NVL8 across agentic AI, HPC, and data analytics workloads:
Use case fit: where NVIDIA HGX Rubin NVL8 excels
Memory capacity, memory bandwidth, and fast GPU-to-GPU communication shape how each workload performs on HGX Rubin NVL8. Here's how that plays out for agentic AI, data analytics, and HPC.
Agentic AI
- Memory footprint and KV cache: With 2 TB of HBM4 memory, HGX Rubin NVL8 comfortably hosts large key-value (KV) caches for million-token context windows, so multiple agent sessions can stay active at once. Single-node deployments execute models and caches seamlessly, and 24 TB/s NVLink bandwidth eliminates fabric latency during tensor-parallel serving.
- Throughput efficiency: With up to 10x higher token throughput per megawatt than previous architectures, you can run concurrent lightweight agents and multi-step reasoning workflows at a lower cost.
Data analytics
- Scale-out pipeline acceleration: GPU-accelerated ETL, dataframe query processing, vector indexing, and embedding generation scale horizontally across nodes using high-bandwidth backend networking.
- Node economics: With 130 TB/s of aggregate memory bandwidth, HGX Rubin NVL8 delivers superior cost-per-row processing and throughput for large-scale data pipelines.
HPC
- Double-precision density: At 265 TFLOPS of FP64 double-precision performance per eight-GPU node, the system efficiently handles scientific simulations, molecular dynamics, and computational finance workloads.
- Unified simulation and AI workloads: High memory bandwidth and fast inter-GPU communication let you run hybrid pipelines that combine classical HPC simulations with AI surrogate models on unified hardware.
Get ready for NVIDIA HGX Rubin NVL8
Coming to CoreWeave Cloud this quarter, NVIDIA HGX Rubin NVL8 brings teams running agentic AI, data analytics, and HPC workloads Rubin-generation performance on an AI cloud purpose-built to put it to work.
Start planning for NVIDIA HGX Rubin NVL8. Request a briefing for capacity planning, onboarding timeline, and workload fit — or request an ARENA Pass to run your workload on HGX Rubin NVL8 yourself.
Want to go deeper? Explore our related resources:
- Engineered for Agentic AI: Exploring NVIDIA Vera Rubin on CoreWeave
- A Deep Dive on CoreWeave Innovations for NVIDIA Vera Rubin NVL72
- Liquid-Cooled Switching Doubles AI Network Bandwidth Per Rack
- 5 Lessons from Building a Multi-Plane Network Fabric for Agentic AI
- What It Takes to Bring Up a Multi-Rack NVIDIA Vera Rubin NVL72 Cluster