MLPerf v6.0 Results

Train bigger and serve faster on the only AI cloud leading MLPerf in both training and inference

More useful work per GPU, on infrastructure purpose-built to keep up with the models you're shipping

What is MLPerf?

MLPerf is an industry-standard benchmark suite that measures machine learning performance across realistic deployment scenarios. The speed at which systems process inputs and generate outputs from a trained model directly influences performance and user experience, making the MLPerf Inference benchmark a critical performance metric for both CoreWeave and our customers.

CoreWeave leads cloud providers in MLPerf Inference v6.1 performance

CoreWeave’s MLPerf Inference v6.1 results show leading performance across today’s most demanding workloads, from multimodal to MoE reasoning models.

Highest multimodal server throughput

On Qwen3-VL-235B-A22B, CoreWeave sustained 1,196 queries per second in server mode and 1,135 samples per second offline on an NVIDIA GB300 NVL72 rack. That is the highest server throughput among cloud providers

Nearly 20% more throughput per GPU

On DeepSeek-R1-671B, derived per-GPU server throughput on NVIDIA GB200 NVL72 rose 19.8% in the five months since MLPerf Inference v6.0, comparing a 72-GPU v6.1 submission with a 64-GPU v6.0 submission.¹

Highest reasoning throughput per GPU

On GPT-OSS-120B, a single NVIDIA GB300 NVL72 rack sustained 16,635 tokens per second per GPU offline and 16,118 in server mode. Both are the highest of any v6.1 Datacenter Closed submission, on any silicon

‍

Left
Right

The pattern across MLPerf v6.0 results is consistent: each new GPU platform on CoreWeave converts directly into shorter training runs and higher inference throughput.

Copied
MLPERF V6.0 RESULTS

‍CoreWeave's MLPerf v6.0 results for training and inference

‍

MLPERF TRAINING V6.0

CoreWeave helps AI pioneers train faster at scale

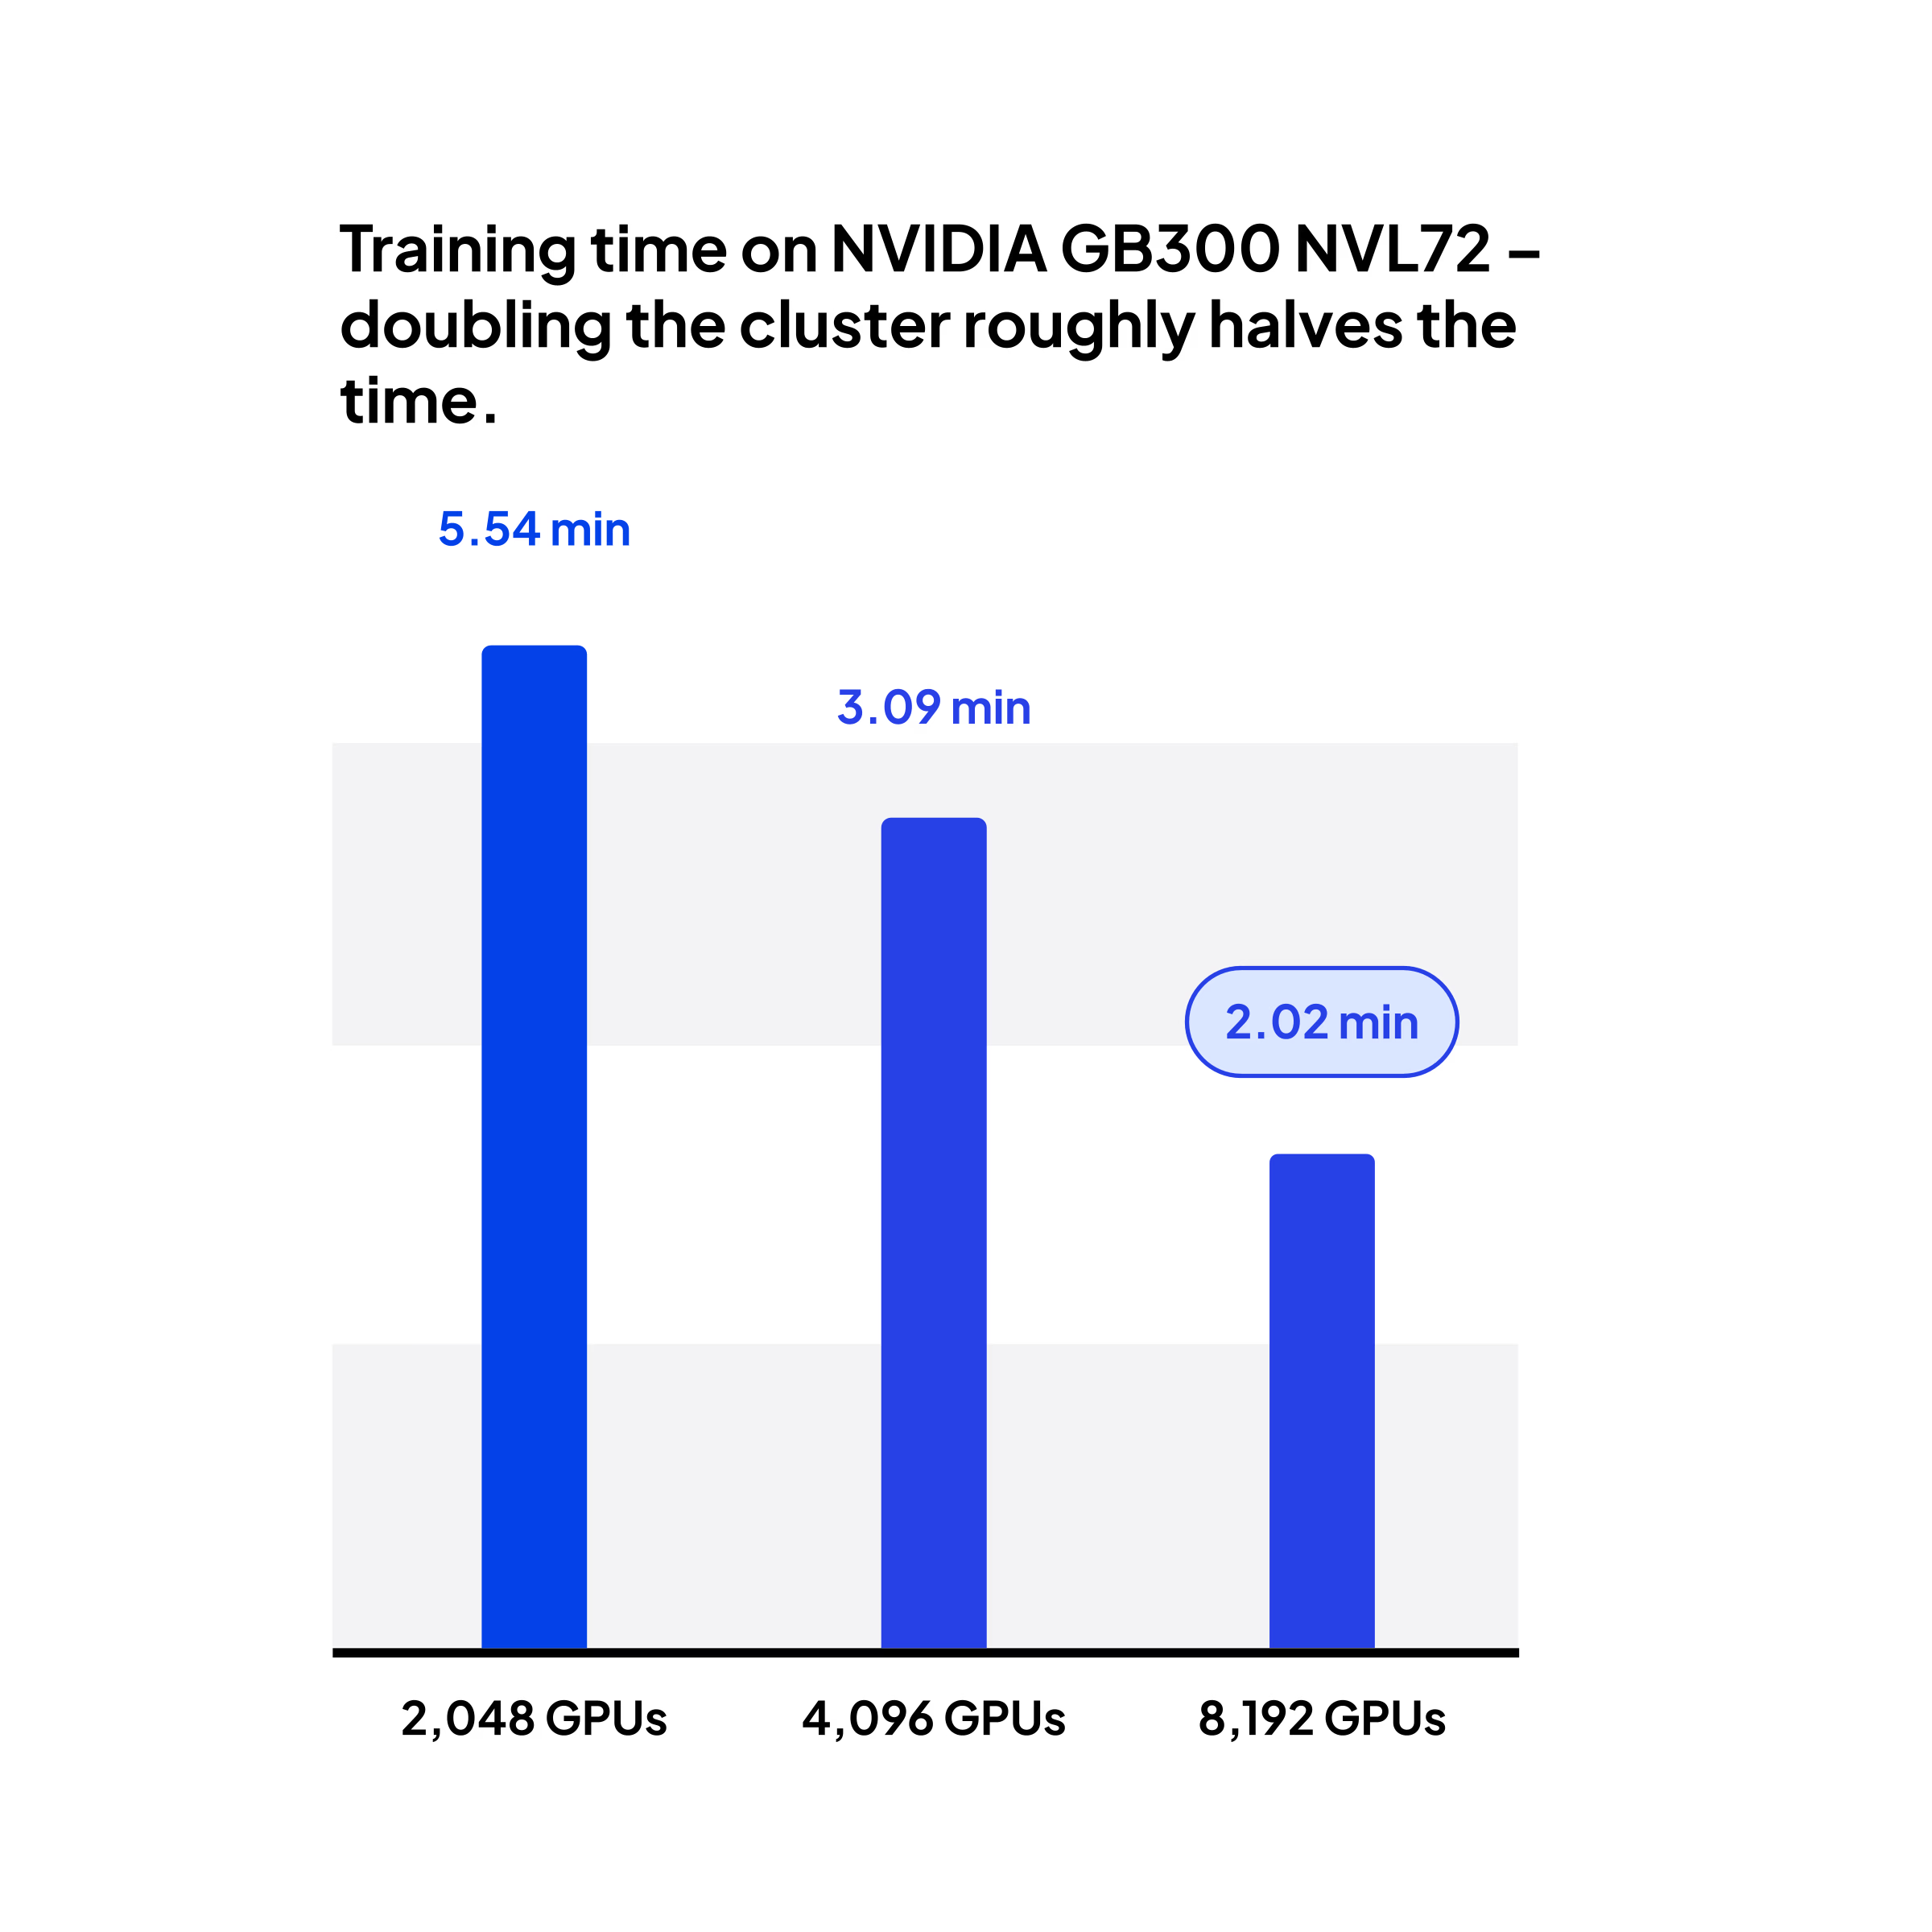
CoreWeave trained DeepSeek-V3 671B benchmark to the MLPerf quality target in just 2.02 minutes on 8,192 NVIDIA GB300 NVL72 GPUs. CoreWeave also trained Llama 3.1 405B in 9.77 minutes on 4,096 NVIDIA GB300 GPUs, delivering a 2.80x wall-clock speedup year over year on an identical benchmark. Scaling from 2,048 to 4,096 GPUs reached 89.6% per-doubling efficiency, and scaling from 4,096 to 8,192 GPUs reached 76.5% per-doubling efficiency.

MLPerf Inference v6.0

CoreWeave delivers unparalleled throughput leadership

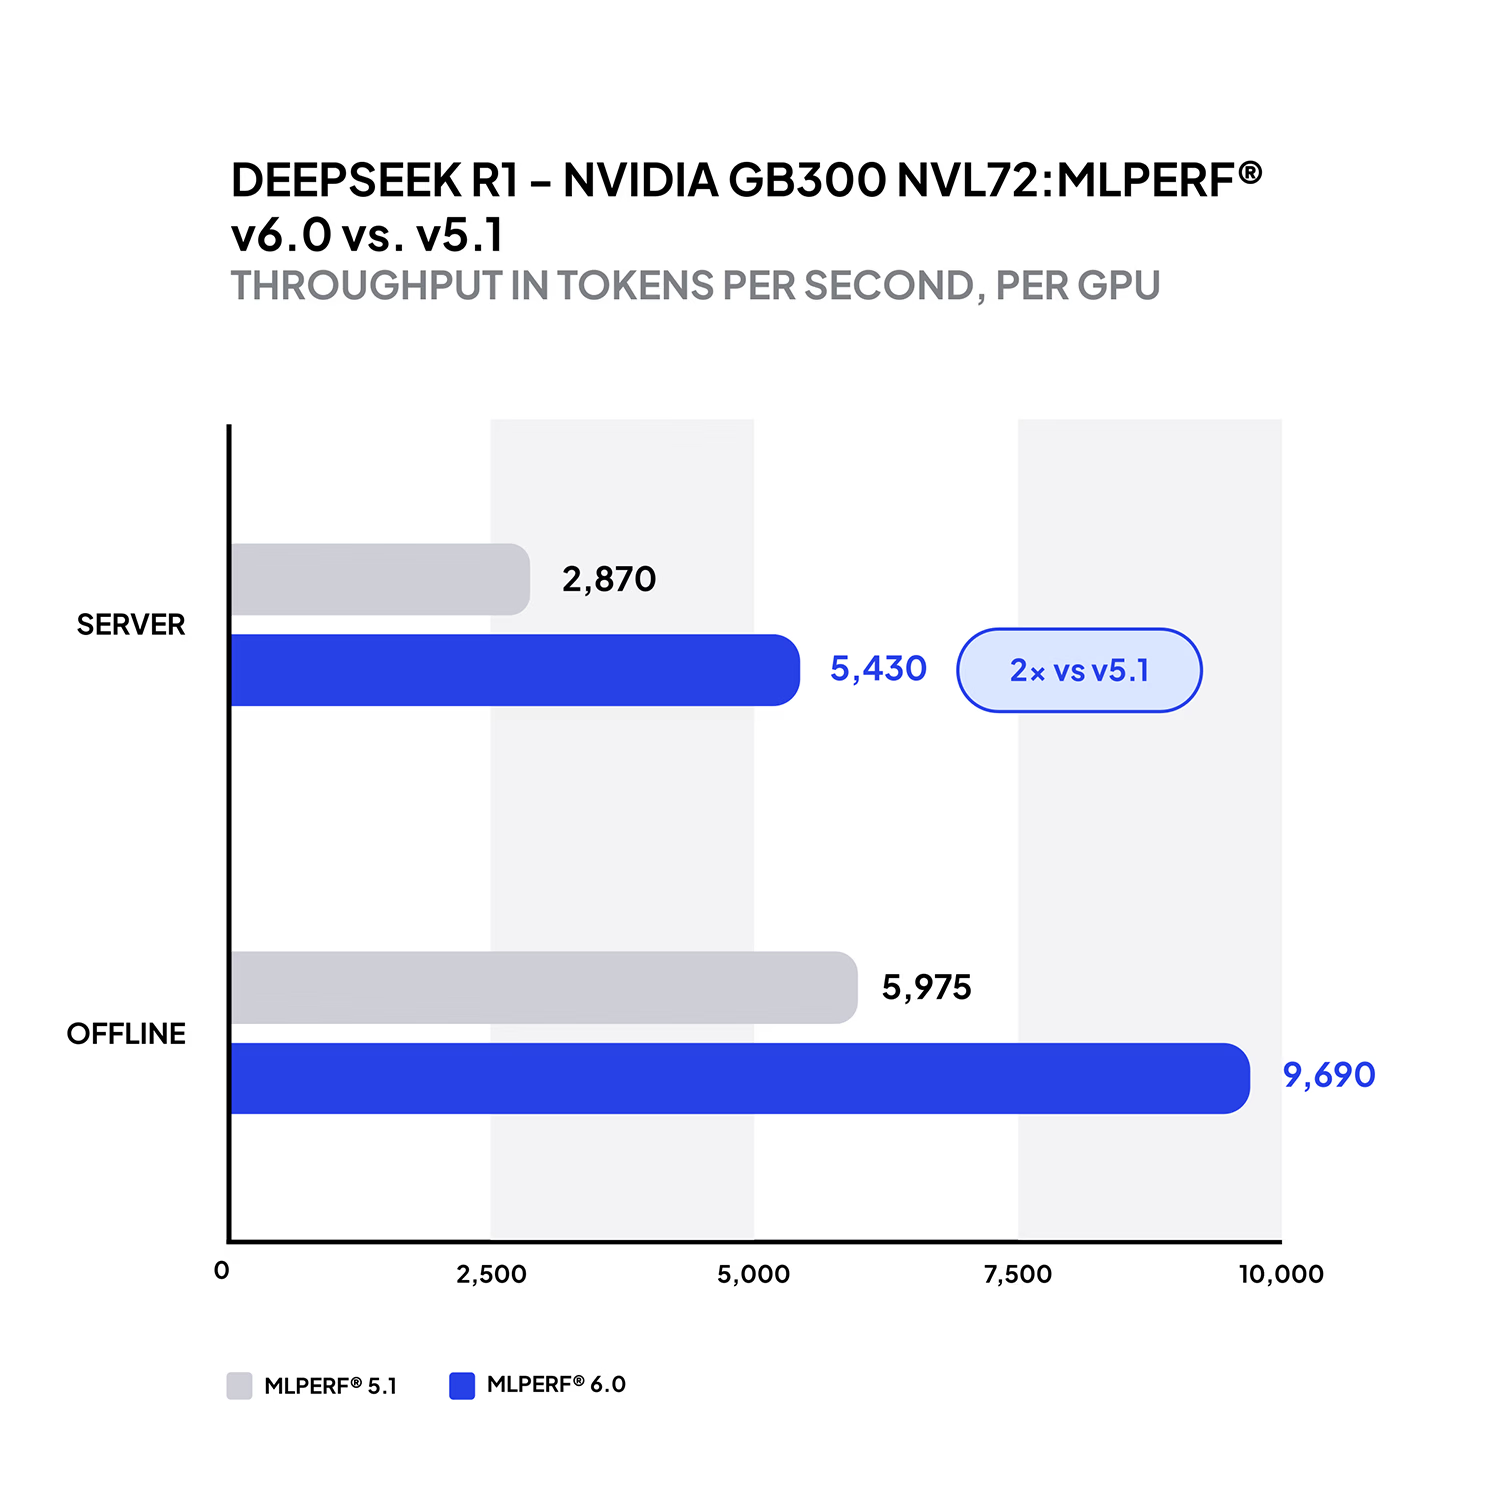
For all of CoreWeave’s submissions in this round, NVIDIA GB300 NVL72 delivered the strongest DeepSeek-R1 performance, leading in offline throughput and per-GPU efficiency. DeepSeek-R1 server throughput increased by more than 14% and offline throughput increased by more than 34% on NVIDIA GB300 NVL72 versus NVIDIA GB200 NVL72. CoreWeave is turning newer GPU platforms into more inference throughput.

‍

MLPERF V5.0 RESULTS

‍CoreWeave’s MLPerf v5.0 results for training and inference

CoreWeave’s MLPerf v5.0 results established clear leadership across both training and inference, with early NVIDIA GB200 NVL72 inference performance and record-setting training scale. Download the whitepaper for the full story.

MLPERF TRAINING V5.0

More than 2 x faster training performance

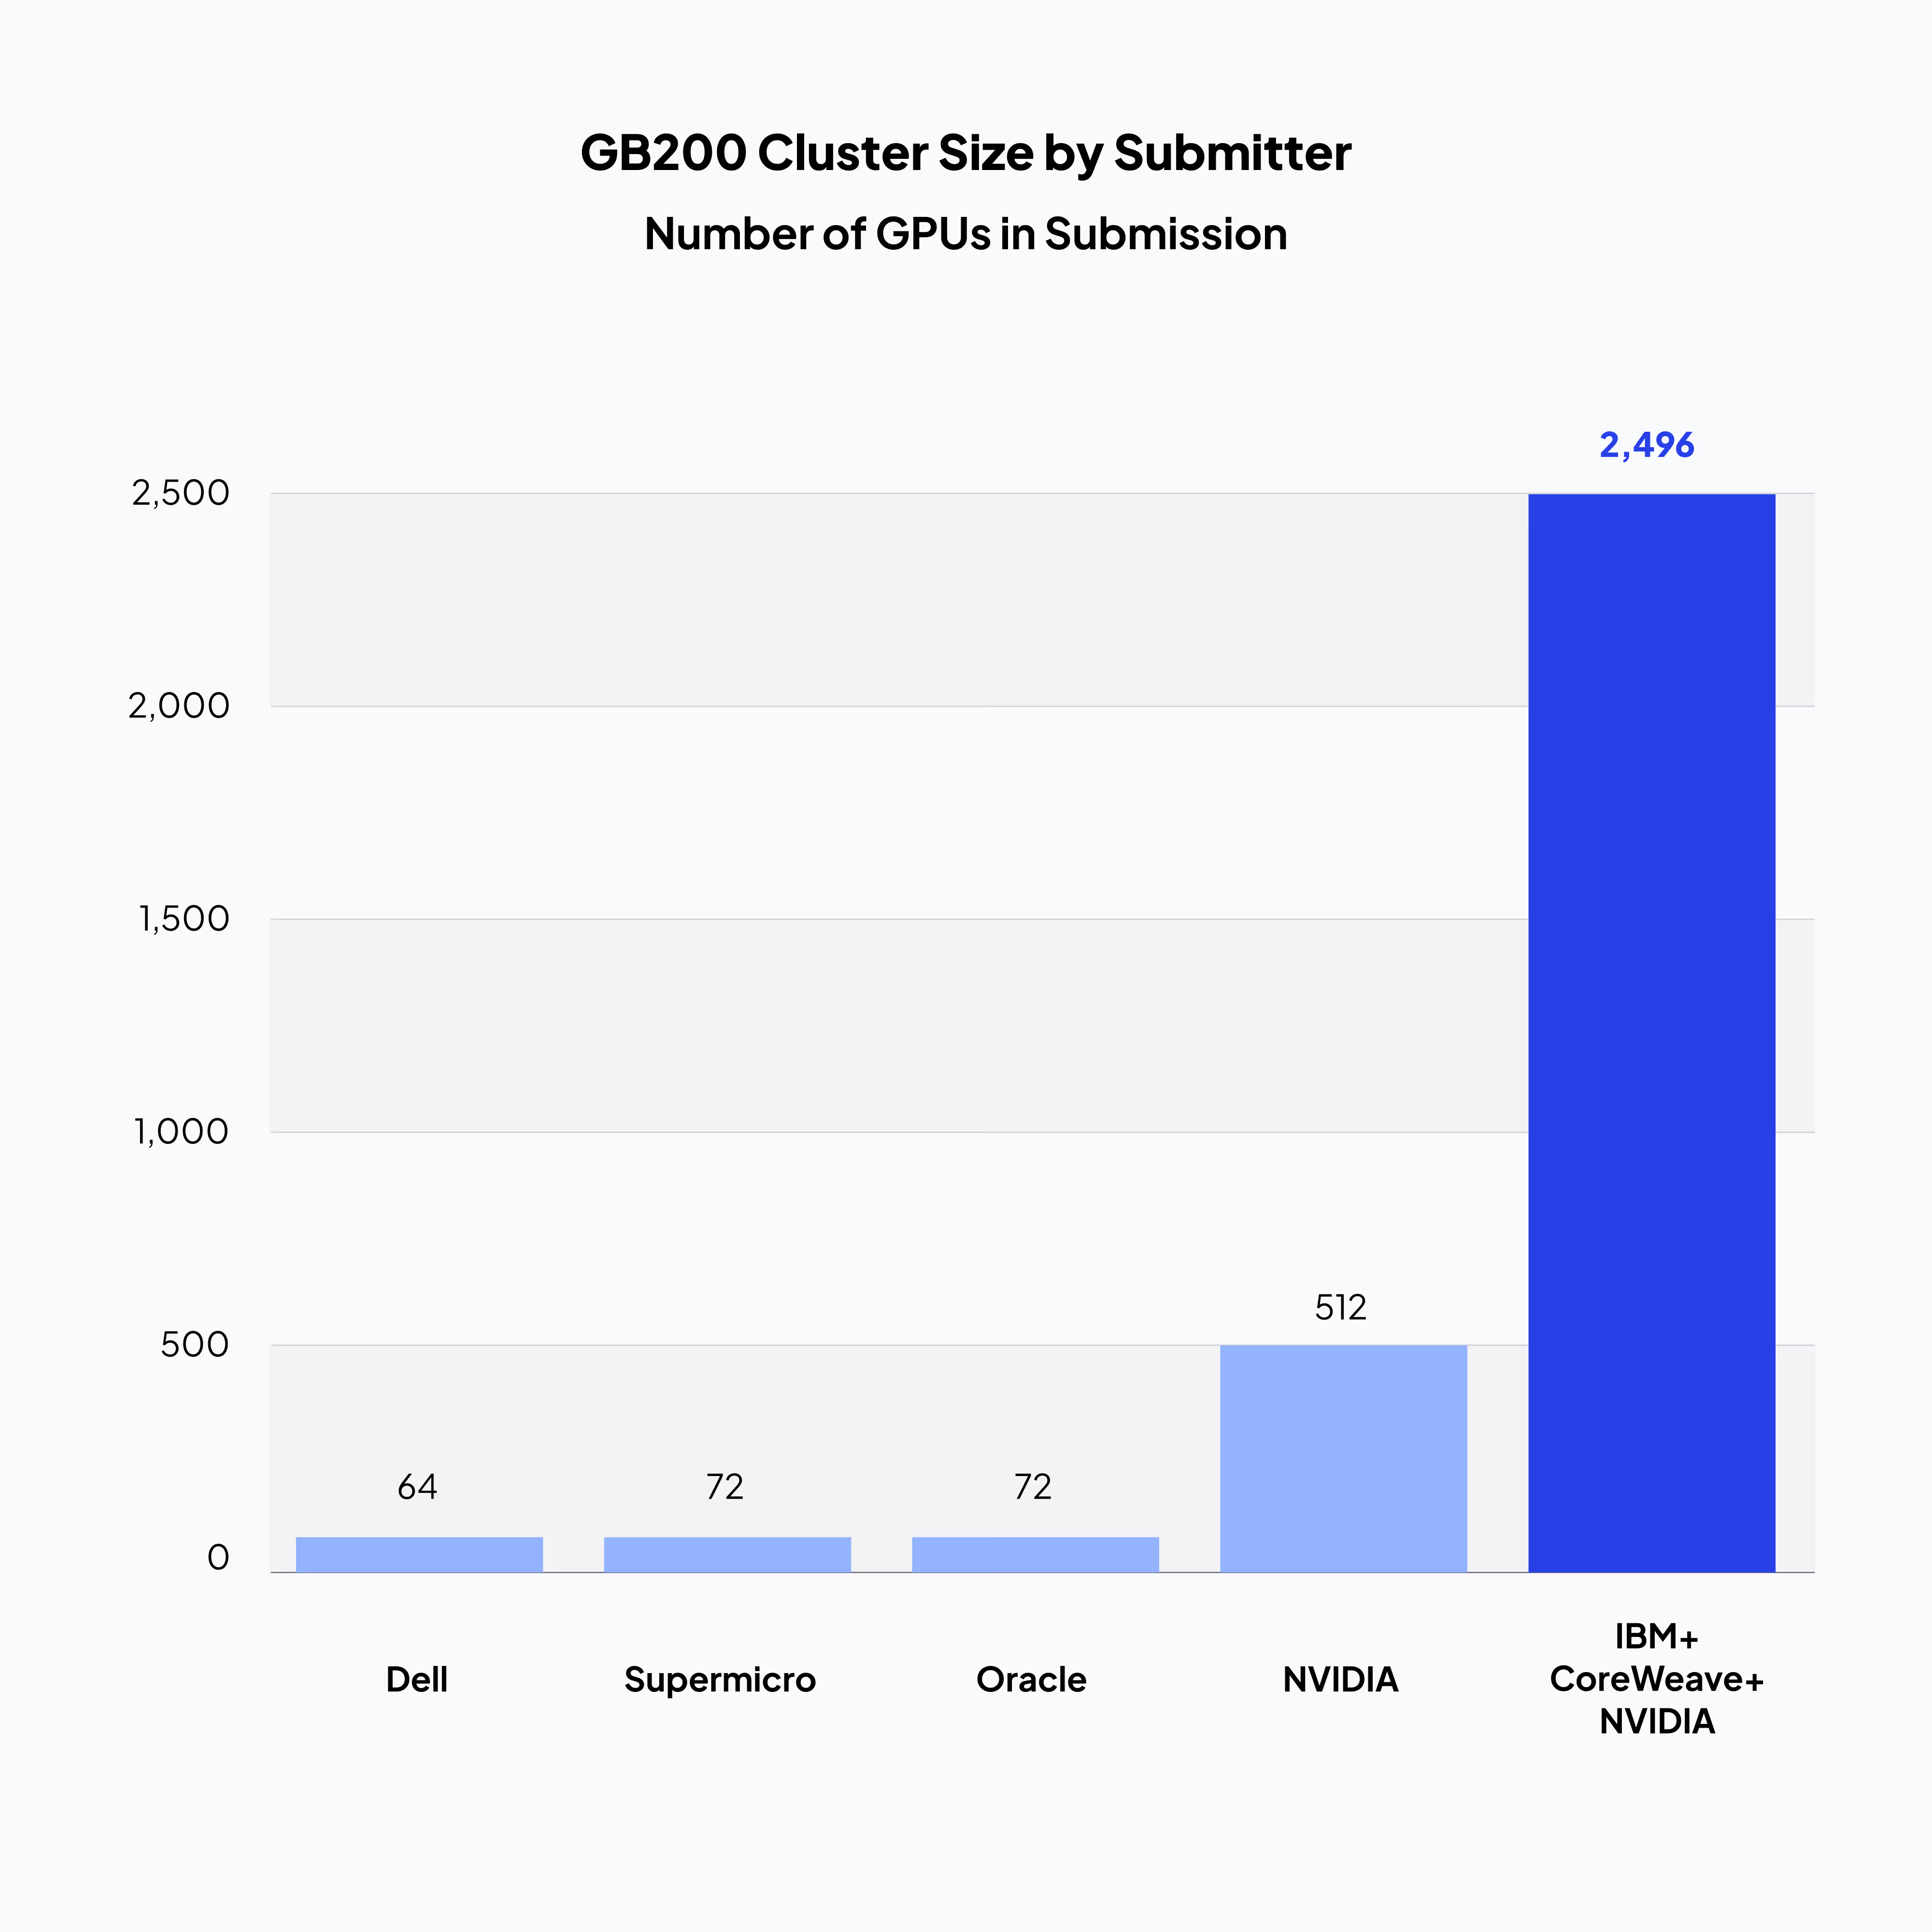
CoreWeave, NVIDIA, and IBM partnered on MLPerf Training v5.0 results, showcasing an NVIDIA GB200 cluster 34x larger than the next largest submission. That scale cut training times to up to twice as fast and gave teams more room to iterate.

‍

MLPerf Inference v5.0

Inference performance built for production speed

CoreWeave is the first and only cloud provider to submit MLPerf Inference v5.0 results on NVIDIA GB200 Grace Blackwell instances, clearing 800 tokens per second on the Llama 3.1 405B model – a 2.86x per-chip gain over NVIDIA H200 GPUs. Our NVIDIA H200 GPU instances reached 33,000 tokens per second on the Llama 2 70B model, 40% more throughput than NVIDIA H100 GPUs. That speed keeps GPUs working and shortens the loop between idea and result.

‍

Trusted by leading AI labs, enterprises, and startups

Rev.com logo
Decart logo
Cloudflare logo
Abridge logo
Jane Street logo
CoreWeave
CoreWeave
WaveForms AI logo
CoreWeave
Fireworks AI logo
Augment logo
CoreWeave
Conjecture logo
Chai logo
Mistral AI logo
NovelAI logo

Frequently asked questions

 What is MLPerf?

Why are MLPerf benchmarks important?

What does MLPerf Training v6.0 measure?

 What does MLPerf Inference v5.0 measure?

How does CoreWeave's performance compare in MLPerf benchmarks?

 What makes CoreWeave GPUs unique for MLPerf results?

Ready to accelerate your roadmap?

Disclaimer‍

Result verified by MLCommons Association. The MLPerf name and logo are registered and unregistered trademarks of MLCommons Association in the United States and other countries. All rights reserved. Unauthorized use strictly prohibited. See www.mlcommons.org for more information.